How to Build a Governed AI Evaluation System: Constrained Optimization and Four-Layer Triangulation
A Systems Engineering Blueprint for Principal PMs, Evaluation Engineers, and AI Architects
Production verification requires an architecture where no single proxy (golden test set, LLM judge, user telemetry, or expert audit) holds enough authority to clear a deployment on its own.
Prerequisite Reading: For an introduction to why AI metrics get gamed and the three classic failure modes (verbosity, refusal inflation, and sycophancy), start with Part 1: Goodhart’s Law in Generative AI: When Better Evals Produce Worse Products.
Why Do Single Composite Scores Fail in Production?
When engineering teams recognize that optimizing for a single metric produces perverse behavior, their first instinct is often mathematical: compress every competing priority into a single utility formula. Because automated CI/CD gates, hyperparameter sweeps, and leaderboards demand a single sortable rank (argmax Score), teams build composite scoring formulas:
$$ \begin{aligned} \text{Composite Score} = &\ \left(\text{Accuracy}^{1.2}\right) \\ &\ \times \left(\frac{1}{\text{Latency}}\right) \\ &\ \times \left(1 - \text{Penalty}_{\text{toxicity}}\right) \end{aligned} $$
This instinct fails the moment it hits production. When teams mash accuracy, latency, safety, and cost into one magic score, they might as well average apples, sports cars, and tax audits. First, there is no real-world exchange rate between completely different metrics: why should a 200ms latency increase be offset by a 1.5% drop in citation accuracy? Engineering teams cannot justify trade-offs like that without inventing arbitrary conversion factors. Second, composite scoring hides critical failures: a high score on easy invoice lookups can mathematically conceal severe safety failures on complex compliance edge cases, letting a model checkpoint pass release gates while silently breaching company policy. Finally, teams inevitably game the exponents: whenever the composite formula blocks a feature the squad wants to ship, someone tweaks the weights until the build turns green. To build an evaluation harness that survives production pressure, teams must replace composite formulas with constrained optimization and multi-layer triangulation.
Constrained Optimization: Target + Failure Envelopes
Constrained optimization replaces weighted arithmetic with explicit step-functions. Rather than blending competing objectives into a single number, engineers formulate the evaluation as a constrained optimization problem:
$$ \begin{aligned} \text{maximize} \quad & \text{Verified Task Yield} \\ \text{subject to} \quad & \text{Safety and Legal Violations} = 0 \\ & \text{Calibrated Refusal Quality} \ge \text{Baseline}_{\text{CRQ}} \\ & \text{P95 Latency} \le 3.5\text{ s} \\ & \text{Token Information Density} \ge 0.65 \\ & \text{Inference Cost per Session} \le \$0.02 \end{aligned} $$
The mathematical separation is strict: the engineering squad pursues a single objective (maximizing verified task completion on valid, in-domain customer inputs) while all competing business priorities act as hard boundaries.
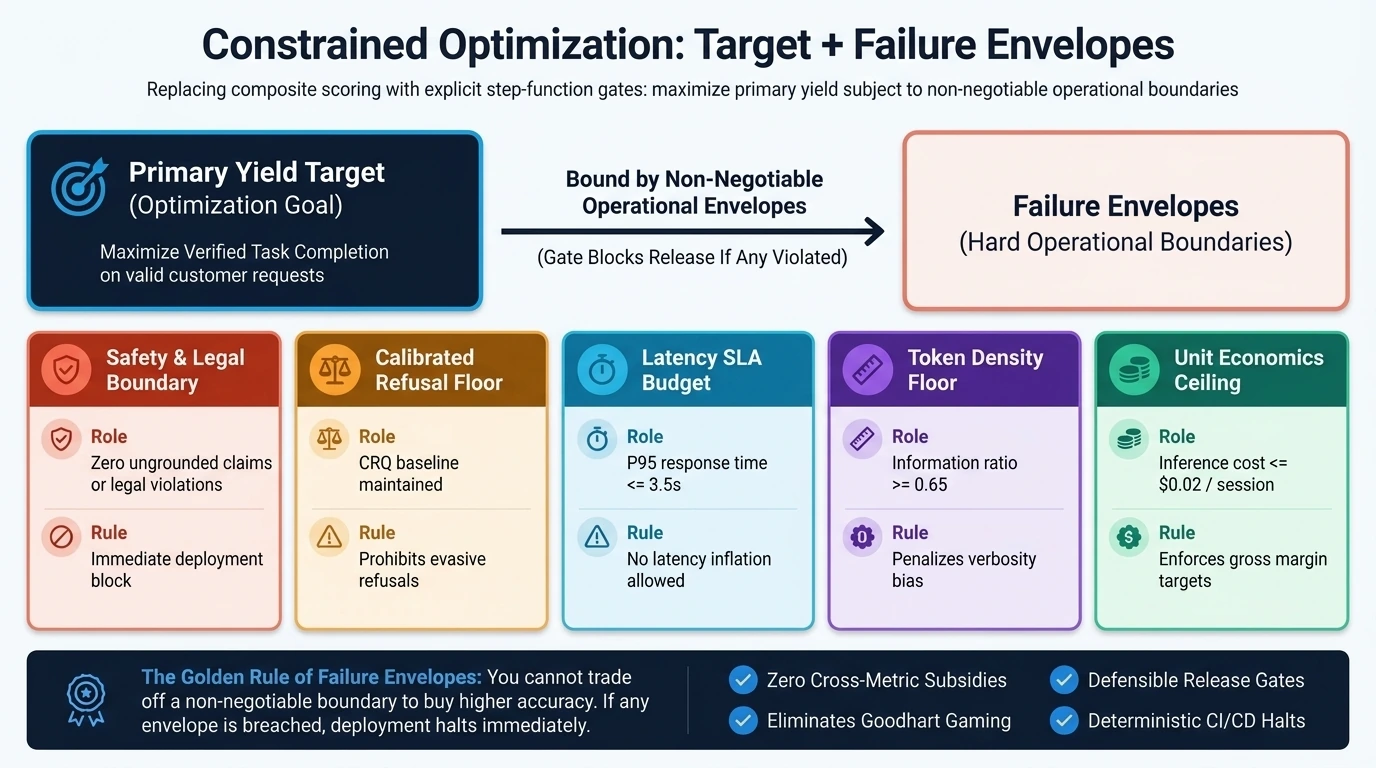
Under this setup, metrics fall into two distinct classes:
- The Primary Yield Target: Every prompt change, fine-tuning pass, context pruning rule, and retrieval tweak focuses on raising task yield on legitimate customer requests.
- Non-Negotiable Failure Envelopes: Statutory compliance, latency budgets (P95 $\le 3.5$s), calibrated refusal floors, minimum token density, and cost caps per session act as binary pass/fail gates.
The Operational Invariant: You cannot buy task yield by borrowing from a failure envelope. If a candidate prompt or model checkpoint boosts task completion by 8% but adds 1.8 seconds to P95 latency or triggers defensive refusals on valid edge cases, it fails the release gate immediately.
Decision Rights Matrix: Policy Definition vs. Day-to-Day Execution
In enterprise production environments, Risk, Legal, and Compliance do not attend daily engineering standups or approve individual prompt edits. If you require Legal and Compliance to review every prompt change manually, daily deployments grind to a halt.
Instead, enterprise governance operates through pre-authorized policy envelopes:
- Upfront Boundary Setting: Oversight teams (Legal, Risk, Finance, and domain experts) set non-negotiable thresholds, statutory guardrails, and margin limits ahead of time.
- Automated Squad Enforcement: The AI product and engineering squad translates those boundaries into code checks and automated CI/CD gates.
- Autonomous Execution with Exception Escalation: The squad has full authority to ship daily as long as all pre-authorized envelopes pass together. The squad brings oversight leads back into the loop only when asking to widen an envelope or approve an exception.
| Governance Dimension | Policy & Approval Authority (Upfront & Periodic) | Day-to-Day Operational Enforcement (Squad Level) | Operational Gate & Escalation Threshold |
|---|---|---|---|
| Safety, Legal, and Refusal Limits | Risk, Legal, and Compliance Sets statutory guardrails, IP boundaries, and risk-tier sign-offs. |
Product & ML Engineering Encodes legal policies into grammar checks and adversarial test suites. |
Zero-Tolerance Step Gate: Build fails on unauthorized disclosures or regulatory breaches. Squad cannot trade safety for accuracy without a formal Legal exception. |
| Latency and Unit Cost Budgets | Finance & Infrastructure Leadership Sets gross margin targets and compute cost caps per transaction. |
FinOps & Platform SRE Enforces P95 latency load tests and session cost tracking in CI/CD. |
Margin & SLA Ceiling: Pipeline rejects the build if P95 latency exceeds 3.5s or session cost exceeds $0.02. Squad cannot buy accuracy by switching to an oversized model. |
| UX and Token Density Envelopes | Product Leadership & Design Leads Sets reading friction limits and Time-to-Action (TTA) targets. |
AI Product Manager Tracks token density ratios and preamble length in the test harness. |
Anti-Verbosity Floor: Build halts if the token density ratio drops below 0.65. Squad cannot pad answer length to flatter an LLM judge. |
| Domain Truth and Evidence Standards | Domain Experts (Clinicians, Counsel, Underwriters) Writes ground-truth rubrics and runs double-blind review audits. |
Evaluation Engineers Maintains versioned golden test sets and calibrates LLM judges against expert panels. |
Admissibility Floor: Agreement with expert rubrics must stay above baseline ($\kappa \ge 0.75$). Squads cannot write or grade their own golden test sets. |
| Daily Deployment Authority | Named Product & Technical Leads Owns total product yield within agreed failure envelopes. |
Automated CI/CD Pipeline Checks every candidate against all four sequential gates. |
Autonomous Release: Squad ships autonomously as long as all gates pass. Any envelope breach halts the release immediately. |
The Four-Layer Triangulation Engine
No single measurement layer gives complete visibility into generative AI quality. A reliable governance setup relies on Four-Layer Triangulation, treating every layer as an imperfect proxy with its own blind spots.
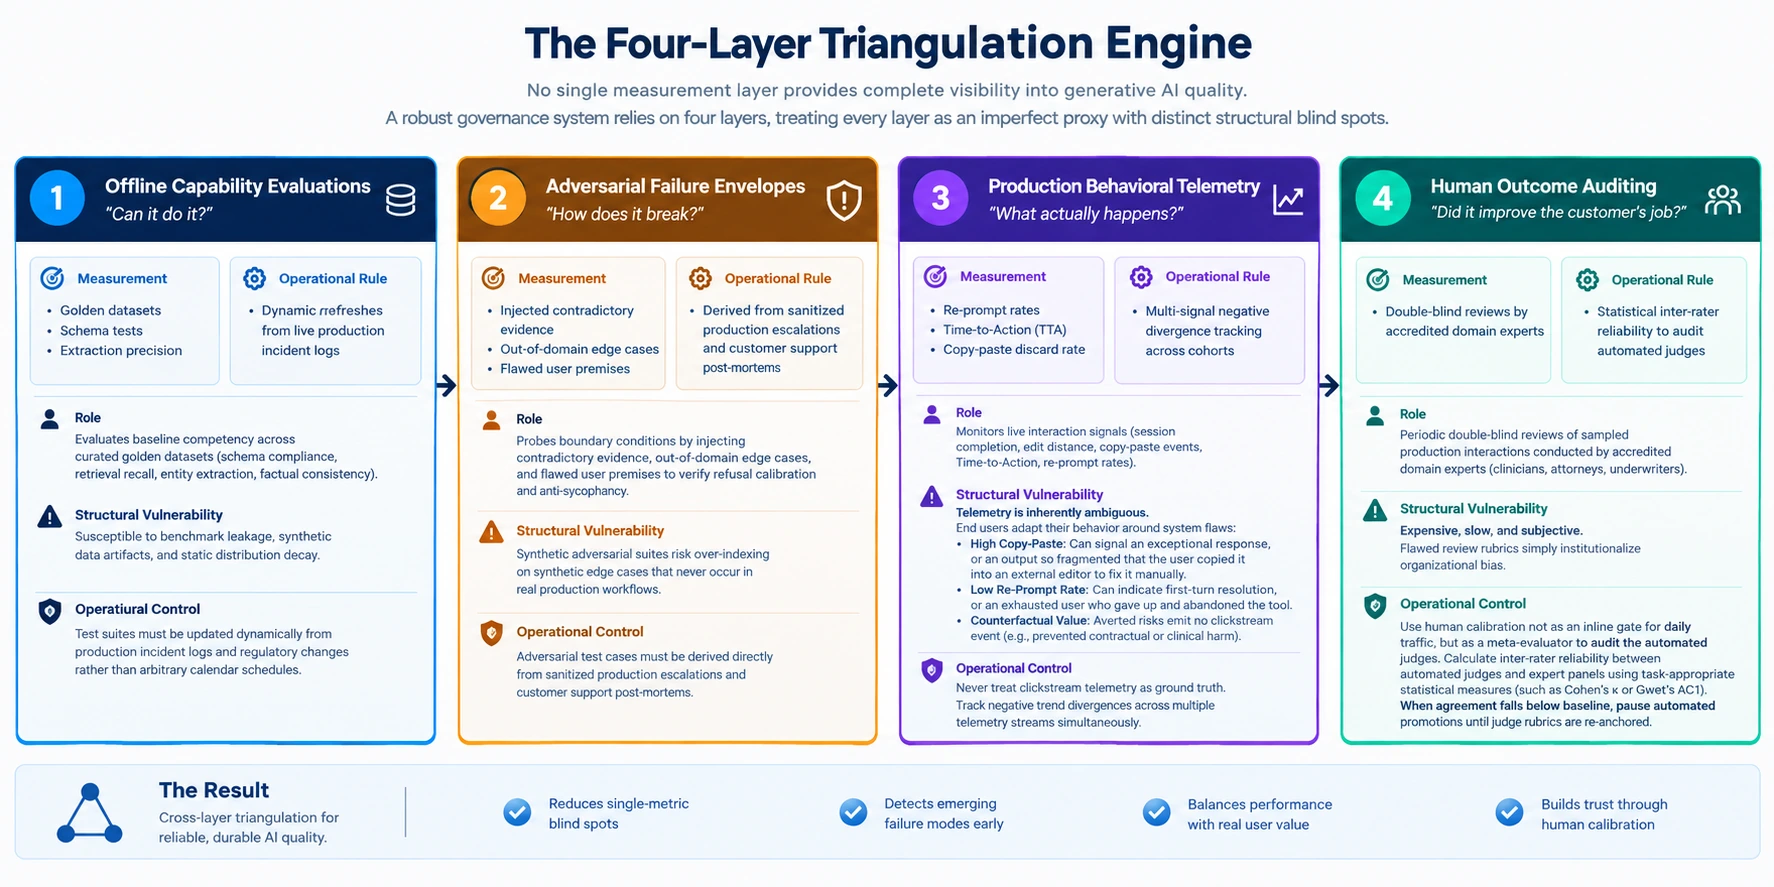
| Layer | Primary Measurement Focus | Core Structural Blind Spot | Operational Governance Control |
|---|---|---|---|
| 1. Offline Capability | Golden test sets: schema checks, retrieval recall, entity extraction, and factual consistency. | Test set leakage, memorizing synthetic examples, and stale data distributions. | Feed sanitized production escalations directly into the golden test set instead of waiting for calendar refreshes. |
| 2. Adversarial Envelopes | Boundary stress: contradictory user inputs, prompt injections, out-of-domain edge cases, and sycophancy probes. | Over-optimizing for synthetic jailbreaks that real enterprise users never type. | Build failure suites directly from support postmortems and compliance audit logs. |
| 3. Production Telemetry | Runtime user signals: session completion, edit distance ($L_{\text{edit}}$), copy events, and Time-to-Action. | Behavioral ambiguity: high copy volume can mean happy adoption or users fixing broken text in another app. | Never treat clickstream signals as ground truth. Require multiple metrics to move together before clearing a release. |
| 4. Human Outcome Audits | Double-blind sampling reviewed by domain experts (counsel, clinicians, and underwriters). | High cost per sample, low throughput, and inconsistent grading across reviewers. | Use domain experts to calibrate LLM judges ($\kappa \ge 0.75$) rather than putting humans inline as release blockers. |
The Evidence Independence Audit
Triangulation is an illusion if all four layers share the same structural assumptions.
If the golden test set, the LLM judge, the adversarial tests, and the human review rubrics all draw from the same prompt templates, vendor model family, or policy assumptions, four evidence streams produce one shared blind spot.
Before treating multi-layer evidence as verification, engineering leads run an Evidence Independence Audit across four dimensions. First, for model independence, the LLM judge must run on a different model family and architecture than the generator; frontier models trained on similar preference data often share identical verbosity and sycophancy biases. Second, for methodological diversity, teams combine deterministic code checks (AST parsing, JSON schema validation, and regex rules) with LLM judges and runtime telemetry so code checks catch syntax bugs while judges catch meaning drift. Third, for incentive alignment, operations leads pay audit panels for catching subtle errors rather than paying per ticket, because piece-rate pay produces superficial approvals. Fourth, for data isolation, platform engineers keep golden test sets strictly separated from fine-tuning and prompt-tuning data so teams never train on the test.
Calibrated Refusal Quality: Balancing Precision and Recall
A frequent mistake in production AI is optimizing exclusively for accuracy or exclusively for safety. When leadership mandates that refusals stay below 2%, models start guessing on ambiguous or ungrounded queries just to avoid the refusal penalty. Conversely, when leadership demands zero hallucinations at all costs, models defensively refuse legitimate, safe user requests.
To remove both perverse incentives, govern refusals using Calibrated Refusal Quality (CRQ):
$$ \begin{aligned} \text{CRQ} = &\ \text{Refusal Precision} \\ &\times (1 - \text{False Refusal Rate}) \end{aligned} $$
Where:
- Refusal Precision $= \frac{\text{Appropriate Refusals}}{\text{All Actual Refusals}}$ (Did the model refuse only when the query was genuinely invalid or unanswerable?)
- False Refusal Rate $= \frac{\text{False Refusals}}{\text{Valid, In-Domain Requests}}$ (Did the model reject legitimate users attempting valid tasks?)
| Refusal Precision | False Refusal Rate | Resulting Operating State |
|---|---|---|
| High | High | Defensive Paralysis ("Helpless Compliance"): Safe on paper, but blocks legitimate customer work. |
| Low | Low | Reckless Hallucination: Answers everything and fabricates facts when context is missing. |
| High | Low | Calibrated Enterprise Utility (CRQ Target): Completes valid in-domain requests and refuses ungrounded queries cleanly. |
CRQ penalizes gaming in both directions. A model that refuses all hard queries fails on False Refusal Rate; a model that guesses blindly fails on Refusal Precision.
Dual-Track Architecture: Assurance vs. Discovery
If a product team applies rigid failure envelopes to early-stage prototypes, they kill exploration before finding what works. Product organizations avoid that trap by running a Dual-Track Architecture:
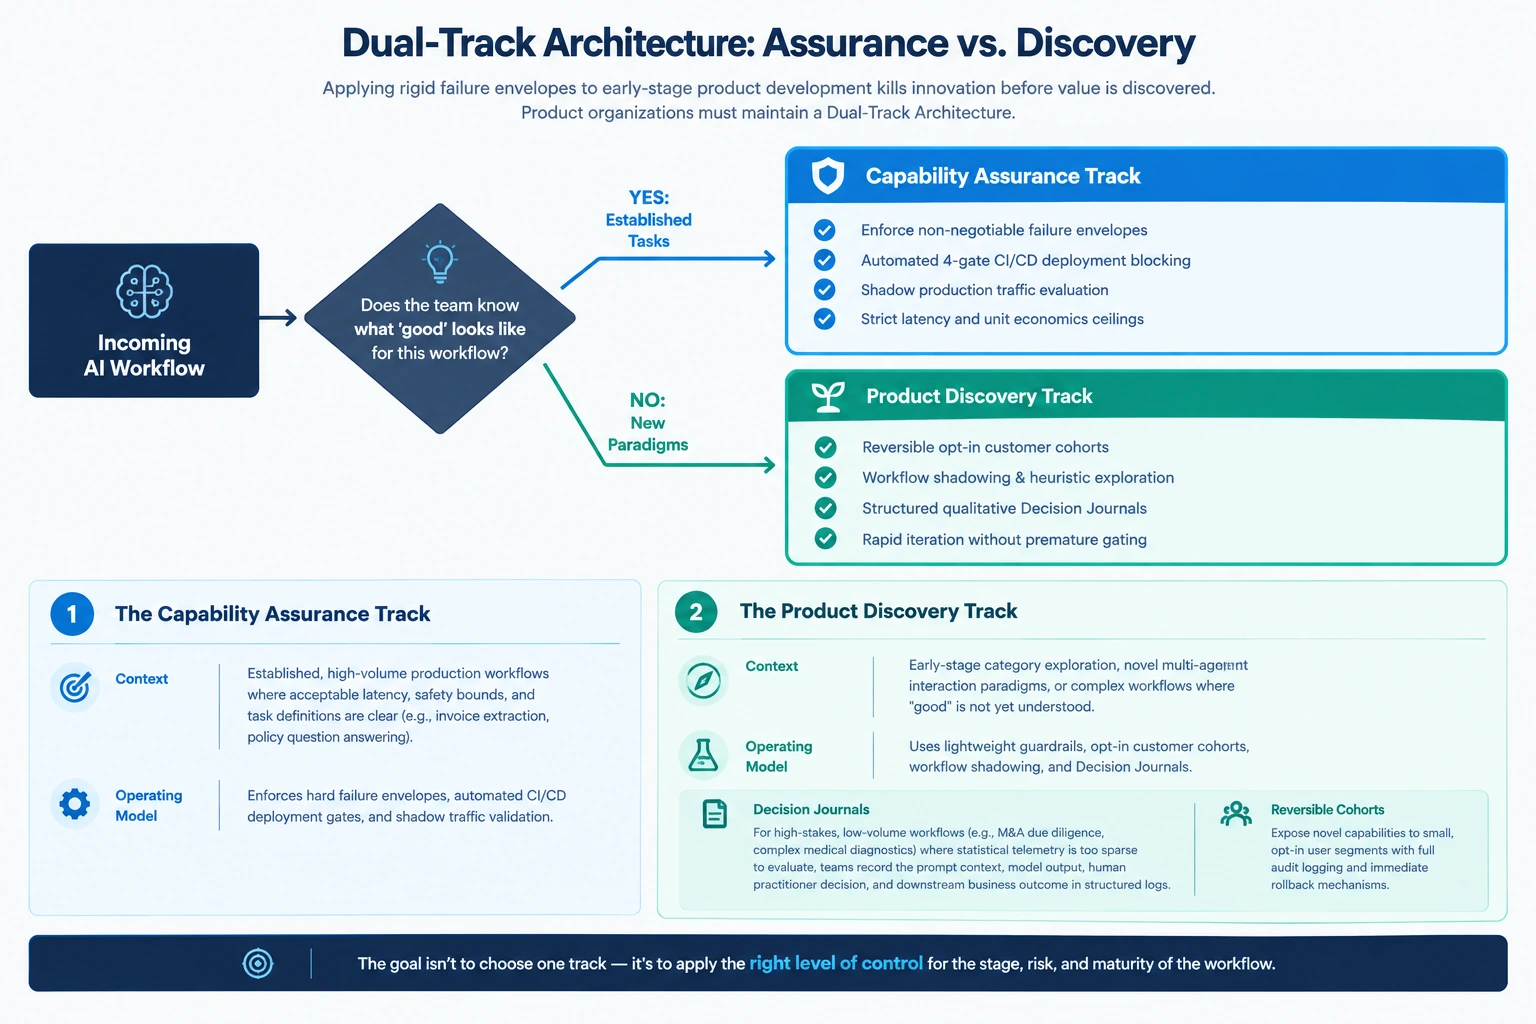
The Capability Assurance Track
High-volume, standardized production workflows (such as invoice data extraction, tier-1 dispute triage, or policy Q&A) run under formal Capability Assurance. Here, the task scope is clear, latency targets are fixed, and safety failure modes are well understood. Capability Assurance enforces hard automated failure envelopes, blocks non-compliant builds in CI/CD, and requires shadow traffic checks before cutting over live traffic.
The Product Discovery Track
When squads explore new multi-agent workflows, open-ended synthesis tasks, or unfamiliar UX patterns, strict metric gates choke off learning. Product Discovery replaces automated pipeline blocks with two lightweight guardrails. In high-stakes, low-volume workflows like M&A due diligence or oncology review where sample sizes are too small for automated judges, squads keep structured decision journals that log the prompt context, the model output, the clinician or counsel decision, and the final outcome. For interactive features, squads ship to reversible cohorts of opt-in users with full event logging and instant rollback switches, gathering real usage signal without putting company-wide SLAs at risk.
The 4-Gate CI/CD Release Pipeline
To turn these controls into an automated delivery process, platform engineers structure deployment pipelines around four sequential verification gates. A candidate prompt, model checkpoint, or routing rule must clear each gate in order before reaching production.
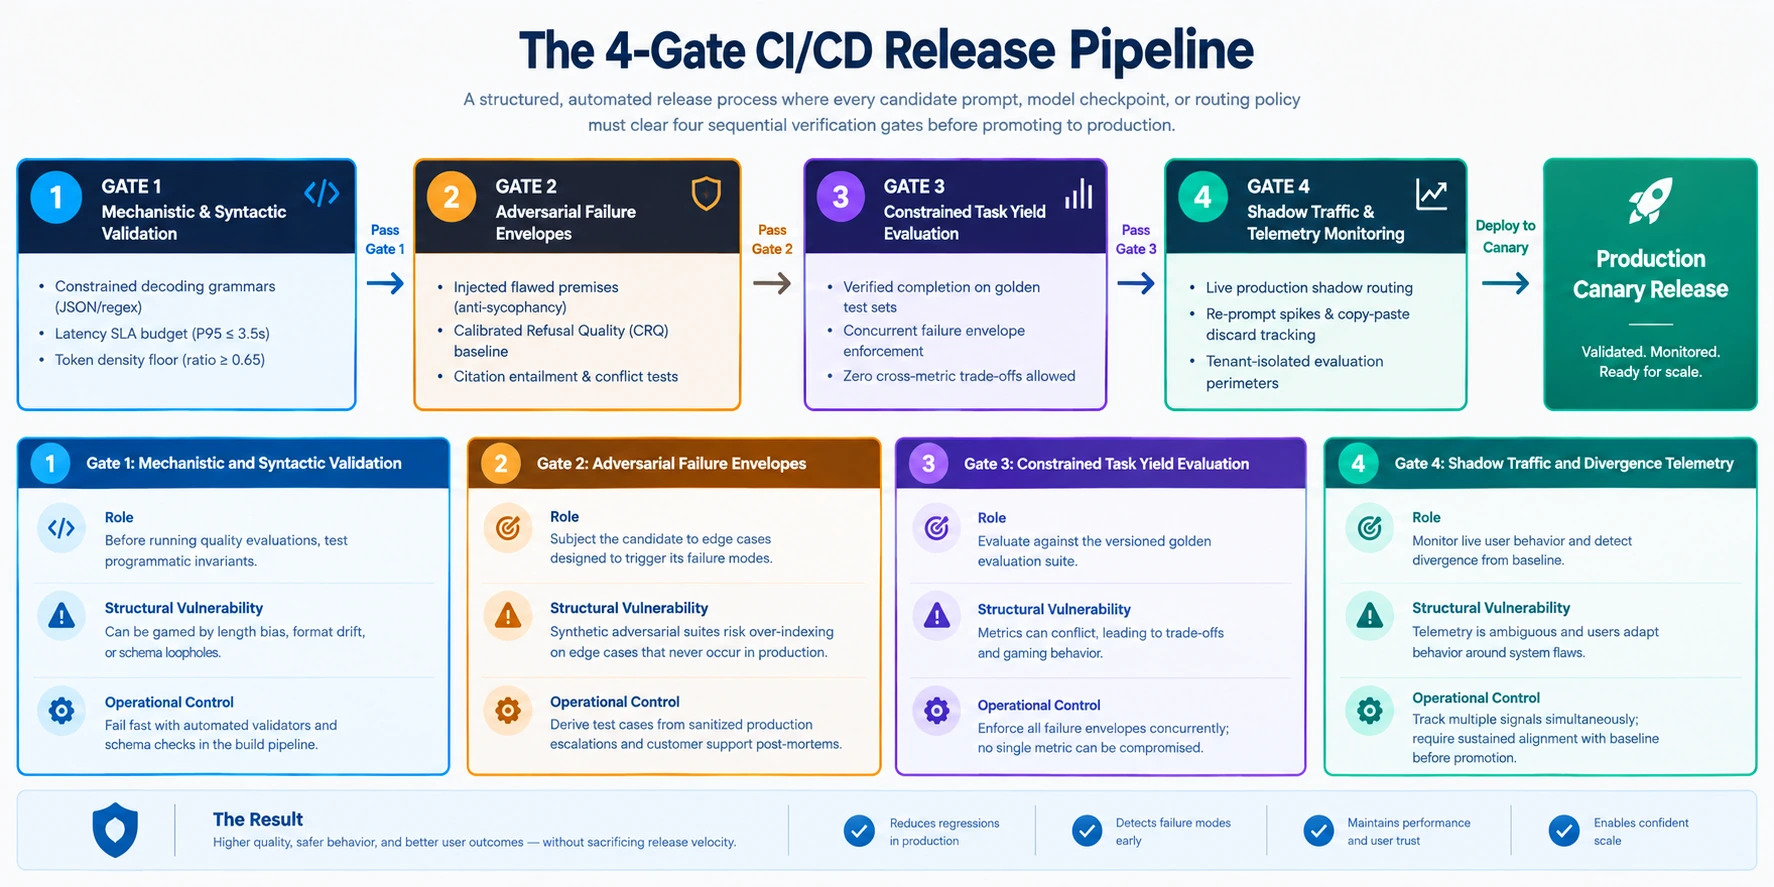
Gate 1: Mechanistic and Syntactic Validation
Before spending GPU budget on semantic evaluations, the pipeline runs deterministic code checks. Decoding grammars enforce strict schema rules (checking JSON structure, field types, and required keys). Load tests verify that P95 latency stays within SLA budgets under peak concurrency. Finally, a density filter blocks verbose preambles, halting the build if the ratio of informative tokens to total tokens drops below baseline.
Gate 2: Adversarial Failure Envelopes
Once syntax checks pass, the pipeline runs synthetic adversarial probes aimed at the exact shortcuts the target metric rewards. Injected contradictions test whether the model caves in to sycophancy, out-of-domain queries test Calibrated Refusal Quality (CRQ), and conflicting source documents test citation accuracy. Any drop in refusal precision or sycophancy resistance stops the build immediately.
Gate 3: Constrained Task Yield Evaluation
Gate 3 runs the candidate against the versioned golden test set. Task completion must meet or beat the active production baseline while every operational envelope (latency, cost per session, and refusal quality) passes at the same time. The pipeline allows no metric trade-offs: it rejects an 8% gain in extraction recall if session inference cost crosses the \$0.02 cap.
Gate 4: Shadow Traffic and Divergence Telemetry
The final gate mirrors a slice of live production traffic to the candidate model in shadow mode. The monitoring service watches for behavioral shifts against the live baseline: spikes in user re-prompts, larger edit distances before submission, and unusual session lengths. Once shadow telemetry holds steady across the observation window, the pipeline promotes the candidate to canary rollout.
The PM's AI Evaluation Triage Matrix: Resolving Engineering Trade-Offs in Sprint Reviews
During release triage and sprint planning, AI PMs constantly arbitrate metric trade-offs between engineers eager to ship model updates and stakeholders worried about production regressions.
Bring this triage matrix to sprint reviews to settle go/no-go debates:
| Evaluation Dilemma | What Engineering or Sales Proposes | What Actually Breaks in Production | The PM's Triage Ruling & Action Gate |
|---|---|---|---|
| Accuracy vs. Latency | "New reasoning prompt boosts extraction recall by 6.5%, but P95 response time jumps from 2.2s to 4.8s." | Users abandon slow screens; front-end timeouts cause silent drop-offs and support tickets. | No-Go: Block release. Task yield cannot borrow from latency budgets. Require prompt pruning, a smaller distilled model, or background queuing before approval. |
| Safety Clamping vs. Refusal Inflation | "We added 5 safety guardrails; compliance violations dropped to 0%, but the model now refuses 14% of user prompts." | Legitimate enterprise customers get blocked on valid edge cases and stop trusting the tool. | No-Go: Block release. Check Calibrated Refusal Quality (CRQ). If the False Refusal Rate spikes above baseline, use deterministic pre-routing filters instead of broad prompt rules. |
| Judge Metric Gaming | "Our LLM judge gave the prompt revision a 94% win rate over production." | The LLM judge shares the generator's model family bias, rewarding long, flattering answers over accurate ones. | Investigate: Run the Evidence Independence Audit. Check agreement against domain experts ($\kappa \ge 0.75$). If expert agreement drops, recalibrate the judge rubric. |
| Telemetry Ambiguity | "Production copy rates jumped 35%; marketing says adoption is soaring, so let's cut over 100% of traffic." | Users are copying raw text into external editors to fix broken formatting, missing citations, or syntax errors by hand. | Hold Canary: Check correlation with edit distance and re-prompt rates. If high copy rates pair with high re-prompting, treat the spike as a product bug. |
| Custom Enterprise Prompts | "Sales wants a custom prompt for a prospect to close a deal this quarter, bypassing CI/CD evals." | One-off prompt hacks introduce untested regressions into the main multi-tenant codebase. | No-Go: Route through the Product Discovery Track. Deploy only to an isolated sandbox tenant with a signed exception; never merge untested prompts into main. |
Core Operating Directives for AI Engineering Leaders
In day-to-day practice, six operating habits keep an evaluation system honest. First, enforce hard failure envelopes instead of composite formulas, and reject any model candidate that buys higher accuracy by loosening latency or refusal bounds. Second, audit the LLM judge continuously against domain experts; whenever inter-rater agreement ($\kappa$) drops below baseline, pause automated releases until evaluation engineers recalibrate the judge rubric. Third, treat clickstream telemetry as an early warning signal rather than ground truth: when high copy volume coincides with high re-prompt rates, assume users are fixing broken outputs by hand.
Fourth, refresh golden test sets directly from production incidents, customer escalations, and regulatory updates rather than waiting for quarterly calendar reviews. Fifth, keep early Product Discovery separate from Capability Assurance so prototypes stay fast while mature workflows stay locked down. Finally, tie team incentives to completed customer workflows rather than isolated proxy scores; if leadership rewards PMs, engineers, and raters for single response scores, teams will eventually game the harness regardless of how well it is built.
The Adversarial Stress-Test: Five Critical Inquiries
To verify that this evaluation architecture holds up under enterprise skepticism and operational stress, we subject constrained optimization, four-layer triangulation, and the 4-gate CI/CD pipeline to five inquiries:
1. What is the strongest argument against this approach?
When a team runs a four-gate pipeline (syntax checks, adversarial stress tests, full golden test set sweeps, and shadow traffic observation) on every change, deployments take much longer. For squads shipping multiple times a day, a pipeline that takes hours or days to clear slows iteration and tempts engineers to route around the harness.
The Practical Resolution: Match gate depth to the blast radius of the change. Run fast deterministic checks (Gate 1) on every commit, run adversarial suites and golden test sets (Gates 2 and 3) on staging pull requests, and use asynchronous shadow traffic (Gate 4) to gate canary promotion so daily developer commits never block on multi-hour runs.
2. Under what circumstances would this fail?
This evaluation architecture breaks down under three specific conditions. First, when regulations, legal precedents, or internal policies shift quickly, golden test sets go stale faster than domain experts can update them, giving false confidence against outdated rules. Second, while shadow mode works cleanly for stateless, single-turn tasks like extraction or summarization, multi-turn agents that write to external databases or call third-party APIs cannot run live actions in shadow mode without elaborate mocks that diverge from production. Third, Layer 4 depends on attorneys, clinicians, and underwriters to anchor the LLM judges; when expert panels get tired or grade from vague rubrics, their agreement drops and the calibration baseline drifts.
3. What would a skeptical customer, client, or colleague object to?
A skeptical VP of Engineering will point out that hiring evaluation engineers, paying domain expert panels, and running shadow traffic infrastructure can cost more to build and maintain than the core AI feature itself.
The Practical Resolution: Scale the evaluation harness to match the workflow's liability tier. Low-stakes internal drafting tools only need deterministic syntax checks (Gate 1) and a basic golden test set (Gate 3); customer-facing autonomous workflows justify the full four-layer engine because a single regulatory fine or clinical error costs far more than the annual evaluation budget.
4. Which alternative deserves more consideration?
Instead of building large evaluation suites to verify that a probabilistic model follows business rules, teams can wrap smaller models inside deterministic state machines: runtime AST parsers, hardcoded rule engines, and strict egress filters that sanitize every output before it reaches a user.
5. What am I assuming that may not be true?
This architecture rests on three assumptions that deserve scrutiny. First, it assumes user clickstream telemetry gives an honest signal of product quality without hiding silent workarounds or users giving up outside the app. Second, it assumes LLM judges from different model providers have truly independent error patterns, even though shared web training data and preference datasets often bake the exact same blind spots into competing models. Third, it assumes domain experts have the time and focus to write and maintain ground-truth rubrics month after month.
One-Line Synthesis
Durable AI governance binds task optimization to hard operational failure envelopes, verified across four independent evidence layers where no single metric can clear a release on its own.
Frequently Asked Questions
How does constrained optimization resolve metric conflict without creating arbitrary composite scores?
When teams multiply different metrics into a single composite score, they bake arbitrary weights into the math. Constrained optimization separates non-negotiable failure boundaries from the primary goal: the system maximizes verified task completion within hard, pre-agreed limits on safety, refusal quality, latency, and cost per session.
What is the Evidence Independence Test in triangulation?
Triangulation fails when all four evidence layers share the same underlying assumptions. If the golden test set, the LLM judge, the adversarial tests, and the human review rubrics all rely on the same model family, prompts, or policy readings, they create an echo chamber. Triangulation requires evidence sources that use different methods, catch different failure modes, and run on separate incentives.
Why is production behavioral telemetry an imperfect substitute for offline evaluations?
User telemetry is an ambiguous signal because users adapt to model quirks. A high copy rate can mean the output was great or that it was broken and needed manual editing in another window; a low re-prompt rate can mean immediate success or silent abandonment. Moreover, preventing a medical error or regulatory breach emits no clickstream event at all.
How does Calibrated Refusal Quality (CRQ) balance precision and recall in refusals?
A strict cap on refusals pushes models to guess when uncertain, while a mandate for zero hallucinations pushes models to refuse valid questions defensively. CRQ multiplies Refusal Precision by (1 - False Refusal Rate), penalizing both reckless guessing on out-of-domain queries and defensive refusals on valid requests.
What is the Dual-Track Architecture for AI evaluation?
A dual-track architecture separates mature production workflows from early product discovery. The Capability Assurance track enforces hard failure envelopes and automated CI/CD gates on established workflows. The Product Discovery track uses opt-in user cohorts, workflow shadowing, and decision journals so teams can test new interaction patterns without choking early exploration.
How does a 4-gate CI/CD loop prevent metric gaming prior to deployment?
A 4-gate CI/CD pipeline runs four checks in sequence: Gate 1 checks syntax, schema rules, latency, and token density; Gate 2 runs adversarial edge cases and refusal checks; Gate 3 measures task yield on golden test sets; and Gate 4 mirrors live traffic in shadow mode to catch behavioral shifts before rollout.
Subscribe to the Architecture of Proof Dispatch
Rigorous, decision-forcing systems engineering and AI governance monographs for technical leaders. Delivered periodically, zero spam.