Perplexity Teardown: Verification Engineering and the Citation Illusion
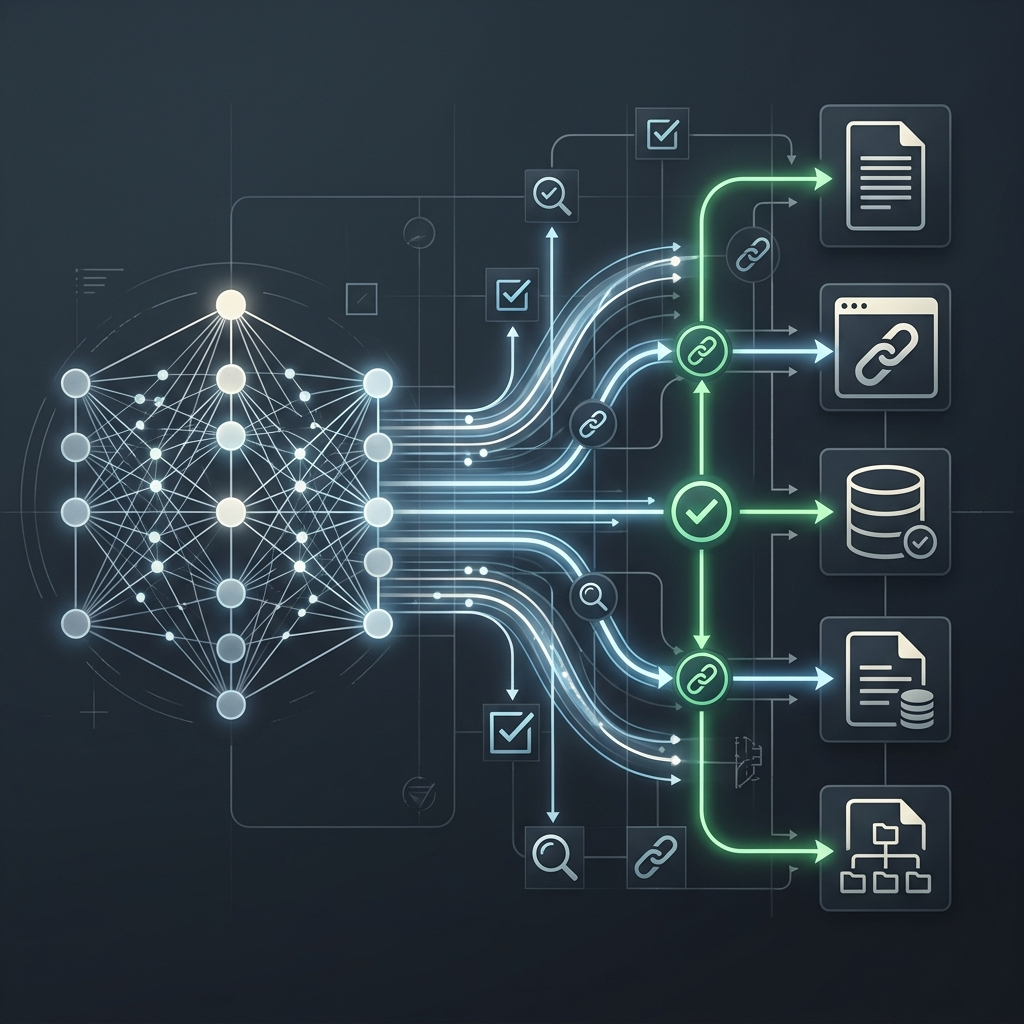
A Systems Engineering & Product Strategy Teardown for Enterprise Architects, Search Engineers, and AI Product Leaders
An ungrounded LLM hallucination is dangerous, but an hallucination decorated with authoritative footnotes is catastrophic. Software citations do not eliminate verification failures; they shift human psychology toward reflexive trust.
Why Does Perplexity Collapse the Retrieval-Synthesis Loop?
The primary failure mode of first-generation generative AI products was confident epistemic detachment: models trained on massive static datasets generated grammatically flawless, authoritative prose that was factually disconnected from current reality.
Traditional search engines resolved this by pushing the entire verification burden onto the user:
-
The search engine returns ten blue links based on PageRank and keyword matching.
-
The user manually opens five browser tabs, parses advertising-saturated web layouts, extracts relevant paragraphs, and mentally synthesizes the answer.
-
The cognitive load and time cost remain entirely with the human operator.
Perplexity AI’s core product thesis was to collapse this trade-off: transforming search from an index lookup into an automated, evidence-conditioned synthesis engine.
Traditional Search Engine Pipeline:
  [ User Query ] --> [ Index Lookup ] --> [ 10 Blue Links ] --> [ Human Reads, Filters & Synthesizes: 10 Min ]

Perplexity Real-Time RAG Loop:
  [ User Query ] --> [ Real-Time Web Retrieval ] --> [ Dense Rerank ] --> [ Grounded LLM Synthesis: 3 Sec ]
                       (Vespa Hybrid Search)          (Top-K Chunks)        (Inline Footnotes Attached)
The fundamental systems challenge of this model is latency-constrained precision. If retrieval takes more than $500\text{ms}$, the user experiences interface lag. If retrieval prioritizes recall over precision, the model context is poisoned with low-quality content farm text, producing confident nonsense with real URLs.
Why Does Vespa.ai Enable Structural Verification at Scale?
Most early enterprise RAG implementations were naive: an engineer chunked text, stored embeddings in a lightweight vector database, performed approximate nearest neighbor (ANN) cosine similarity search, and dumped the top-5 chunks into an LLM context window.
In production web-scale search, that architecture fails catastrophically:
-
Pure vector embeddings fail on keyword-exact queries (e.g., specific part numbers, legal case names, stock tickers, or recent dates).
-
Standalone vector databases cannot handle high-throughput, continuous document ingestion while executing low-latency queries at thousands of queries per second (QPS).
-
Vector similarity measures semantic closeness, not document authority, freshness, or source credibility.
Perplexity resolved this by building its retrieval tier on Vespa.ai, an open-source search and serving engine designed for multi-stage computation.
| Retrieval Dimension | Naive Vector DB Approach | Perplexity / Vespa Hybrid Architecture |
|---|---|---|
| Search Mechanism | Pure dense vector ANN (cosine distance). | Hybrid Search: Dense vector embeddings + sparse BM25 lexical tokens evaluated concurrently. |
| Index Freshness | Batch re-indexing runs (hours to days old). | Real-Time Mutation: Sub-second document insertion, updating, and garbage collection. |
| Re-Ranking Pipeline | Top-$K$ vector distance cutoff. | Two-Stage Tensor Re-Ranking: Machine-learned cross-encoders evaluate semantic relevance, domain authority, and freshness in-process. |
| Latency Budget | $400\text{ms} - 1200\text{ms}$ multi-hop retrieval. | Sub-$200\text{ms}$ Execution: Joint vector-lexical execution on co-located CPU/GPU nodes. |
By executing dense semantic search and sparse lexical matching in the same computational pass, the system ensures that queries containing exact proper nouns (such as "SEC Form 10-K Section 1A filing for NVDA 2026") retrieve exact text spans rather than generically similar articles.
What Is the Citation Illusion and Why Does It Cause Epistemic Laundering?
While inline citations solve the problem of opaque hallucination, they introduce an insidious secondary failure mode: The Citation Illusion (Epistemic Laundering).
The Citation Illusion: The psychological phenomenon whereby human users dramatically reduce their critical skepticism when an AI output includes numbered footnote links, regardless of whether the cited text actually supports the asserted claim.
In high-stakes enterprise workflows, an answer with five authoritative-looking footnotes creates a false sense of security. Under rigorous audit, citations fall into three distinct integrity classes:
| Citation Integrity Class | System Behavior | Epistemic Failure Mechanism |
|---|---|---|
| Class A: Pinpoint Grounding | The assertion maps $1:1$ to an explicit fact in an authoritative primary source. | Optimal State. Defensible, verifiable, and forensically sound. |
| Class B: Semantic Mischaracterization | The model cites an authentic, reputable source, but distorts a narrow finding into an absolute generalization. | High Risk. The user checks the domain (nature.com, wsj.com), sees it is legitimate, and assumes the claim is true without reading the fine print. |
| Class C: Synthetic Feedback Loops | The model cites an SEO aggregator or AI-generated content farm that recycled earlier unverified AI outputs. | Severe Contagion. Circular confirmation bias where hallucinated assertions cite each other as independent ground truth. |
The Compound Probability of Verified Truth
For a generated assertion to represent verified truth, it must satisfy a strict compound probability condition:
$$P(\text{Verified Truth}) = P(\text{Source Integrity}) \times P(\text{Retrieval Precision}) \times P(\text{Semantic Alignment})$$
-
$P(\text{Source Integrity})$: The probability that the underlying scraped document is authentic, non-spam, and factually accurate.
-
$P(\text{Retrieval Precision})$: The probability that the chunks selected by the search engine contain the relevant context without truncation bias.
-
$P(\text{Semantic Alignment})$: The probability that the LLM faithfully synthesizes the source's findings without extrapolation, omission of counter-evidence, or sycophantic framing.
If an enterprise system evaluates only the model's confidence or checks that a URL returns HTTP $200\text{ OK}$, it ignores the decay across the chain. If $P(\text{Source}) = 0.90$, $P(\text{Retrieval}) = 0.85$, and $P(\text{Alignment}) = 0.85$, the compound probability of verified truth drops to $65\%$, representing a failure rate of one in three transactions decorated with real footnotes.
How Does Perplexity Map to the Architecture of Proof Control Tiers?
To evaluate where Perplexity operates safely and where its boundaries degrade, we map its capabilities across the Architecture of Proof Control Tiers:
| AoP Control Tier | Functional Boundary | Perplexity System Implementation | Operational Failure Modes & Vulnerabilities |
|---|---|---|---|
| Tier 0: Observe & Suggest | Model drafts text and aggregates research; human retains 100% decision rights. | Default Search & Answer Surface. Generates synthesized paragraphs with inline citation badges. | Source authority bias; superficial summarization of paywalled documents; headline-only scraping. |
| Tier 1: Act in Sandbox | Bounded, multi-turn execution within isolated research containers. | Perplexity Pro Search / Deep Research. Iterative multi-query decomposition, multi-source scraping, and structured report drafting. | Incomplete source convergence; looping on conflicting web claims; excessive latency on complex multi-hop queries ($15\text{s}$ to $45\text{s}$). |
| Tier 2: Act with Breakers | Autonomous execution of external actions (e-commerce purchasing, API execution). | Buy with Pro / Agentic Checkout. Function-calling tools that interact with merchant gateways to execute orders. | Severe Risk. Non-deterministic product matching, inventory race conditions, unauthorized payment commits, and absence of signed audit ledgers. |
| Tier 3: Human-Only Air-Gap | Consequential legal, clinical, and statutory truth determinations. | Strictly Excluded. System terms explicitly disclaim legal, financial, or medical fiduciary standing. | Statutory non-compliance and unhedged professional liability if users deploy cited search outputs into formal regulatory filings. |
What Are the Real Unit Economics of Generative Search?
The financial architecture of generative search reveals a brutal unit economic reality: web retrieval turns a low-cost query into a high-cost multi-hop computational workflow.
$$\text{Query Cost} = C_{\text{crawl}} + C_{\text{vespa_rank}} + C_{\text{embed}} + \left( C_{\text{prefill}} \cdot N_{\text{retrieved_tokens}} \right) + \left( C_{\text{gen}} \cdot N_{\text{output_tokens}} \right)$$
| Search Query Type | Operational Execution Path | Estimated Per-Query Cost | Traditional Google Ad Model Parallel |
|---|---|---|---|
| Traditional Keyword Query | Inverted index lookup; zero LLM inference. | $\$0.0003$ | Highly monetizable via sponsored keyword auctions. |
| Perplexity Standard Query | Hybrid Vespa search + scraping top-5 URLs + 4k context LLM synthesis. | $\$0.008 – \$0.015$ | $25\text{x} - 50\text{x}$ more expensive; difficult to monetize with banner ads without destroying UI trust. |
| Perplexity Pro / Deep Research | Query decomposition (4 sub-queries) + 20 URL scrapes + multi-stage reasoning. | $\$0.080 – \$0.350$ | $250\text{x} - 1,000\text{x}$ more expensive; requires high-tier recurring subscriptions ($20/mo) to avoid insolvency. |
Because generative search replaces ten blue links with a single synthesized answer, it eliminates the traditional ad-click real estate that funded web search for thirty years. To survive, generative search engines must either:
-
Charge Heavy Subscriptions: Restricting full capability to high-paying prosumers ($200–$500/year).
-
Introduce Sponsored Answer Injections: Allowing advertisers to bid on being cited as a source, re-introducing the conflict of interest that eroded user trust in traditional search engines.
How Does Perplexity Compare to the Enterprise Proof Standard?
| Evaluation Criterion | Perplexity Consumer Architecture | Architecture of Proof Standard |
|---|---|---|
| Attribution Granularity | URL-level hyperlink badge | Bates-stamped coordinate mapping [Doc ID, Page, Line] |
| Failure Response | Inferred probability when evidence is missing | Explicit calibrated negation ("Refuse to assert without anchor") |
| Source Integrity Check | Algorithmic domain rank (PageRank / TrustRank) | Cryptographic document hash and publisher signature verification |
| Audit Custody | Ephemeral browser thread | Append-only Decision State Vector (DSV) committed to ledger |
| Agency Boundaries | Open-ended agentic browsing and purchasing | Strict Control Tier bounding with automated circuit breakers |
The PM's Generative Search Verification Matrix: 5 Gates for Retrieval & Synthesis Reviews
When product teams evaluate generative search, enterprise RAG, or synthesis engines, traditional document recall metrics ($Hit@k$, $MRR$) obscure downstream business and liability risk. Use this matrix in PRD reviews and architecture gates to audit whether your search pipeline provides forensic verification or cosmetic confidence.
| Review Gate | Architectural Vulnerability | The Fatal Shortcut | Forensic Verification Test | Pass / Fail Production Criteria |
|---|---|---|---|---|
| 1. Citation Binding | Epistemic Laundering | Hyperlink badge pointing to top-level domain without span alignment | Natural Language Inference (NLI) premise-hypothesis entailment | Generated claim must strictly entail the exact cited snippet ($Score > 0.92$) |
| 2. Chunk Provenance | Poisoned / Stale Index | Passing unversioned text chunks from ephemeral scraper threads | Cryptographic chunk hashing (SHA-256) and Bates-coordinate stamping |
Every snippet carries immutable Doc_ID, commit hash, and line range |
| 3. Adversarial Ingestion | Indirect Prompt Injection | Ingesting raw HTML/DOM nodes containing hidden CSS or malicious instructions | AST sanitization and dual-channel segregation between data and instruction context | System strips executable scripts, hidden styling, and semantic prompt overrides |
| 4. Calibrated Negation | Hallucination on Low Recall | Forcing synthesis when retrieved chunks fail relevance thresholds | Deterministic refusal to assert when evidence is absent | Zero speculative filler; engine emits structured negation: "Evidence absent in verified corpus" |
| 5. Unit Margin Gate | Negative Margin on Complex RAG | Blended $0.002 query pricing hiding multi-hop retrieval and reranking costs | Granular COGS accounting: retrieval compute + reranker + inference tokens | P99 query cost capped at target unit economic threshold ($< 15\%$ of gross query value) |
What Survives an Adversarial Stress-Test of Generative Search?
To determine the architectural durability of Perplexity's generative search model, we subject the system to five decision-forcing inquiries:
1. What is the strongest argument against this approach?
The Objection: Perplexity operates at the mercy of two structural choke points: the open web crawling ecosystem and foundation model compute providers. Incumbent search engines possess an amortized web crawl spanning decades, control over consumer browser endpoints, and massive operational margins funded by mature advertising auction engines. Furthermore, as major publishers aggressively erect crawl barriers, paywalls, and copyright litigation against AI search engines, third-party search wrappers face escalating API costs, per-query scraping fees, and a deteriorating content supply chain.
The Practical Resolution: Decouple high-assurance retrieval from the volatile open web by implementing bounded, cryptographically authenticated private data connectors. Enterprise verification engines should index authoritative, contracted document repositories—such as SEC EDGAR, regulatory archives, internal Confluence graphs, and curated technical documentation—rather than relying on unvetted public crawl sweeps. By isolating enterprise queries to pre-indexed, verified corpora and caching verified extraction graphs, organizations eliminate open-web scraping vulnerability and control per-query inference costs.
2. Under what circumstances would this fail?
The Failure Mechanism: The system fails when synthetic content feedback loops pollute the retrieval index (model autophagy), when malicious web actors inject adversarial prompt payloads into indexed HTML spans, or when courts mandate per-publisher licensing for real-time summarization. In the presence of indirect prompt injection hidden within scraped CSS or DOM nodes, an untrusted web page can commandeer the generation context, forcing the model to emit attacker-controlled claims backed by real, indexed URLs.
The Practical Resolution: Implement strict dual-channel architectural segregation between data retrieval and model instruction channels. Retrieved web content must be ingested through sandboxed AST parsers that strip executable markup, hidden DOM elements, and semantic instruction overrides before reaching context assembly. Downstream assertions must pass through an automated NLI (Natural Language Inference) entailment classifier that mathematically proves premise-to-hypothesis alignment between the raw scraped span and the generated sentence before rendering the response to the user.
3. What would a skeptical customer, client, or colleague object to?
The Skeptical Pushback: Enterprise compliance officers and research directors object that hyperlink badges provide an illusion of verification rather than forensic proof. A footnote proves only that a web page was retrieved; it does not prove that the generated text faithfully reflects the source document or that the source itself meets evidentiary standards. Furthermore, public web answers offer negligible utility for private enterprise questions locked inside proprietary data warehouses.
The Practical Resolution: Replace superficial URL footnotes with Bates-stamped coordinate citations [Doc_ID, Commit_Hash, Page, Paragraph, Sentence_Span] linked to immutable raw document snapshots cached in an append-only audit store. Every generated assertion must provide an inspectable side-by-side diff highlighting the exact source span, the extraction confidence score, and the model's calibrated uncertainty score, giving auditors immediate forensic recourse.
4. Which alternative deserves more consideration?
The Counter-Architecture: Deterministic Knowledge Graphs and Grammar-Constrained Claim Extraction represent a superior foundation for enterprise truth verification. Instead of prompting an unconstrained LLM to generate free-form text from unstructured HTML chunks, a structured system executes deterministic entity-relation extraction into an auditable graph. A constrained decoding engine then limits generative output strictly to assertions that map directly to verified graph paths.
The Practical Resolution: Deploy a hybrid two-tier extraction pipeline. For exploratory research, use real-time dense-sparse retrieval to generate candidate hypotheses. For production decisions and regulatory artifacts, route candidate queries through grammar-constrained decoding engines that emit assertions strictly derived from verified Knowledge Graph triples. If an asserted entity-relation triple lacks a corresponding verified graph path, the engine deterministically issues a structured refusal.
5. What am I assuming that may not be true?
The Latent Vulnerability: The architecture assumes that end users actively verify citations, that the public web will remain permissionless and scrapable, and that per-query dynamic RAG is more cost-effective than model parameter fine-tuning. If user telemetry reveals that users treat footnotes purely as aesthetic credibility signals without clicking them, or if web publishers wall off content behind bot-detection barriers, the entire real-time synthesis model collapses under unsustainable scraping overhead and degraded source data.
The Practical Resolution: Instrument user telemetry to track citation interaction rates, dwell time, and downstream verification workflows. Simultaneously, measure the cost-per-verified-query curve against pre-computed domain index caches. When a domain becomes paywalled or scrapers encounter blocking, the system must trigger automated fallback alerts and fall back to verified internal archival snapshots rather than synthesizing speculative text from snippet crumbs.
One-Line Synthesis
Defensible enterprise intelligence demands coordinate-level verification and tamper-evident decision ledgers that bind synthetic assertions directly to primary evidentiary spans.
Frequently Asked Questions
What is the core architectural innovation of Perplexity AI?
Perplexity couples real-time web retrieval directly to generative inference using a high-throughput hybrid search engine (Vespa.ai), enforcing inline source attribution as a structural invariant rather than a post-hoc decorative attachment.
What is the 'Citation Illusion' (Epistemic Laundering) in generative search?
The Citation Illusion occurs when an AI system generates a plausible assertion and decorates it with real footnotes, inducing human users to lower their verification vigilance even when the cited source is low-quality SEO spam or does not mathematically support the generated claim.
Why does Perplexity rely on Vespa.ai rather than standard vector databases?
Standard vector databases struggle with simultaneous dense semantic vector search, BM25 keyword matching, real-time index mutation, and complex attribute filtering within a sub-200ms latency budget. Vespa allows unified hybrid retrieval and tensor re-ranking at massive web scale.
How does Perplexity map to the Architecture of Proof Control Tiers?
Perplexity operates primarily as a Tier 0 (Observe & Suggest) search engine and Tier 1 (Sandboxed Multi-Source Research) synthesis tool, but faces severe safety boundaries when attempting Tier 2 autonomous transactions (such as automated purchasing or multi-agent browsing).
What is the mathematical condition for verified citation truth?
A citation is only evidentially valid if the compound probability of source authenticity, retrieval relevance, and semantic alignment is strictly verified: P(Truth) = P(Source) × P(Retrieval) × P(Alignment).
Subscribe to the Architecture of Proof Dispatch
Rigorous, decision-forcing systems engineering and AI governance monographs for technical leaders. Delivered periodically, zero spam.